Machinelearning,made inNew York

Data scientist at Gartner. Built an AutoML platform from scratch, trained detectors on live city intersections at Columbia, and shipped LLM systems for cybersecurity. I like the whole pipeline, from messy data to something people use.

Open to conversations · 2026

Aishwarya Patange
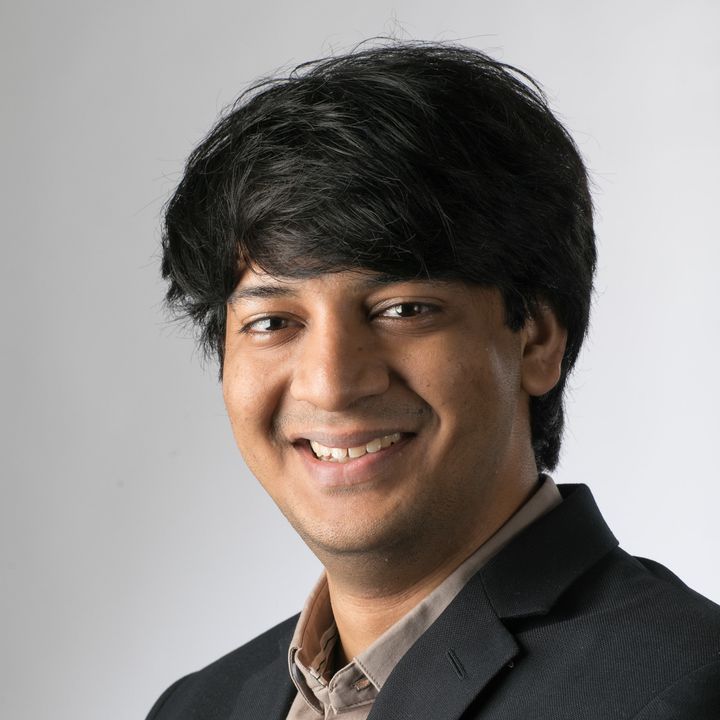
Portrait of Aishwarya Patange

Five years of turning messy data into things people use

I started in Mumbai as an electronics engineer who spent more time training models than soldering boards.

  • 5+years building ML
  • 4cities, two continents
  • 12+open-source projects

That turned into building torsha.ai, an end-to-end AutoML platform, at iQGateway in Bangalore. Then a master’s at Columbia, where I trained detection and tracking models on real intersection footage for the COSMOS smart-city testbed and taught deep learning as a TA. Today I do data science at Gartner, working out of the Stamford office and still living in New York.

What I care about: models that hold up outside the notebook. Clean data pipelines, honest evaluation, explainability, and the engineering that gets a model in front of people.

Four cities, one direction

World map showing the route from Mumbai to Bangalore to New York, with Stamford as the current office
  1. Mumbai, India · 2017 – 2021

    Where it started

    B.E. in Electronics & Telecommunication at the University of Mumbai, top 10% of the class. Built a wearable assistant for the visually impaired and realized I would rather train models than tune circuits.

  2. Bangalore, India · 2021 – 2022

    First production ML

    Associate Data Scientist at iQGateway. Led the design of torsha.ai, an end-to-end AutoML platform, and learned what it takes to get a model in front of paying users.

  3. New York, USA · 2022 – 2023

    Columbia & COSMOS Labs

    M.S. in Electrical Engineering, ML & Data Science track. Trained YOLOv8 detectors on live intersection feeds, cut streaming latency to 80 ms, and TA’d Neural Networks & Deep Learning.

  4. Stamford, USA · 2024 – now

    Gartner

    Data science at Gartner, with the office in Stamford and home still in New York. Retention analytics: probabilistic account scoring across 10,000+ enterprise clients, and the evaluation framework behind an internal RAG assistant.

Where the work happened

  1. Jun 2024 – Present · Stamford, CT · based in New York

    Data Science at Gartner (opens in new tab)

    Retention and growth analytics for Gartner’s enterprise client base, owning the models that tell account teams which relationships need attention and why.

    • Architected and launched the Implied Value Rating model, an account-level probabilistic score covering 10,000+ enterprise clients at 94% accuracy, now in production triggering proactive retention action and contributing to a $295M revenue opportunity.
    • Engineered the feature pipeline behind the customer segmentation and propensity models, combining behavioral engagement signals with MiniLM topical embeddings into cohort-level features that lifted AUC by 7% over an unsegmented baseline.
    • Partnered with Sales Analytics on next-best-program targeting and recommendation models, batch-scoring 134.5K prospects and projecting $40M in savings from discontinuing low-performing programs.
    • Stitched two disparate internal sources, Surveys and Case Studies, into a single unified layer, owning the path from raw documents through the extraction pipeline to the OpenSearch indexes served at query time.
    • Built the evaluation framework for Research Desk, an internal RAG assistant, from scratch on Langfuse, pairing LLM-as-a-Judge checks for numeric grounding, fact attribution, and named-entity correctness with Precision@K and Recall@K per query category, lifting retrieval pass rate from 43% to 78% and factual accuracy by 13%.
    94%IVR prediction accuracy
    $295Mrevenue opportunity
    78%RAG retrieval pass rate, from 43%

    Python, MiniLM, OpenSearch, Langfuse, RAG, LLM-as-a-Judge

  2. Jan 2023 – Dec 2023 · New York, NY

    Computer Vision Research at COSMOS Labs, Columbia University (opens in new tab)

    Computer vision for the Smart City Intersections project on the NSF COSMOS testbed, under Prof. Zoran Kostic.

    • Trained and fine-tuned YOLOv8 models to detect and track vehicles, pedestrians, and two-wheelers from live intersection cameras, reaching 0.79 mAP.
    • Built a semi-supervised, model-assisted data engine inspired by Segment Anything to automate data collection for tracking, lifting model performance by 20%.
    • Designed custom TCP and UDP streaming protocols for the testbed, cutting video streaming latency to 80 ms.
    • Represented Columbia in the NSF Center for Smart Streetscapes, an Engineering Research Center.
    0.79mAP, detection & tracking
    +20%model performance
    80 msstreaming latency

    PyTorch, YOLOv8, OpenCV, Python, TCP/UDP

  3. Jun 2023 – Sep 2023 · New York, NY

    Software Development at ChaosTrack Inc. (opens in new tab)

    LLM-powered incident-response simulation for cybersecurity teams.

    • Shipped three major product features across a Node.js, REST, GraphQL, Hasura, ArangoDB, PostgreSQL, and Docker stack.
    • Built an LLM application that simulates and scores corporate incident responses, using spaCy, NLTK, PyTorch, and Hugging Face.
    • Used LangChain and LangSmith for prompt engineering, improving GPT responsiveness by 35% and output accuracy by 25%.
    • Ran retrieval-augmented generation experiments with Milvus and semantic search with OWL-ViT and Wav2CLIP embeddings.
    +35%model responsiveness
    +25%output accuracy
    3features shipped

    LangChain, Hugging Face, Milvus, Node.js, GraphQL, Docker

  4. May 2021 – Jul 2022 · Bangalore, India

    Machine Learning Engineering at iQGateway (opens in new tab)

    Core developer of torsha.ai, an end-to-end AutoML and data science platform.

    • Led the design and development of torsha.ai, an end-to-end data science platform with AutoML, model explainability, and custom DAG-based pipelines for training and evaluation.
    • Built the platform’s data visualization module with Plotly and D3.js.
    • Raised AutoML pipeline prediction accuracy by 15% with custom scikit-learn-compatible estimators.
    +15%AutoML accuracy

    Python, scikit-learn, AutoML, Plotly, D3.js

Things I built, and what they did

Streaming ML

2023

Real-time stock prediction (opens in new tab)

Sentiment analysis on 5M+ daily tweets streamed through Pub/Sub, Apache Beam, and Dataflow into BigQuery, improving price prediction by 12% over the baseline.

+12%prediction lift
5M+tweets / day

Python, Apache Beam, BigQuery, Google Cloud, NLP

LLM · Retrieval

2024

LLaMA 2 with RAG (opens in new tab)

Retrieval-augmented generation with LLaMA 2 running fully on a local machine, backed by a vector database for grounded answers over private documents.

LLaMA 2, RAG, Vector DB, Python

NLP · From first principles

2024

Transformer from scratch (opens in new tab)

English to Italian neural machine translation with a 6-layer encoder–decoder transformer written from scratch in PyTorch. Trained on OPUS Books with TensorBoard monitoring.

PyTorch, Transformers, Attention, Hugging Face Datasets

The pipeline I ship with

No proficiency bars. These are the tools behind the work above, grouped the way a project actually flows. Anything with a red mark has shipped in something on this page.

Data & Infra

Getting data in, at scale, reliably.

  • Apache Spark (used in Credit default prediction)
  • Apache Beam (used in Real-time stock prediction)
  • Dataflow (used in Real-time stock prediction)
  • BigQuery (used in Real-time stock prediction)
  • Pub/Sub
  • PostgreSQL (used in ChaosTrack)
  • MongoDB
  • ArangoDB (used in ChaosTrack)
  • Docker (used in ChaosTrack)
  • Google Cloud
  • Linux
  • Git

Modeling

Training, evaluating, and explaining models.

  • Python (used in Everything)
  • PyTorch (used in COSMOS Labs)
  • TensorFlow
  • scikit-learn (used in torsha.ai)
  • Hugging Face (used in ChaosTrack)
  • YOLOv8 (used in COSMOS Labs)
  • OpenCV (used in COSMOS Labs)
  • AutoML (used in torsha.ai)
  • SHAP / Explainability (used in torsha.ai)
  • R

Retrieval & LLMs

Grounding language models in real data.

  • LangChain (used in ChaosTrack)
  • LangSmith (used in ChaosTrack)
  • RAG (used in ChaosTrack)
  • Milvus (used in ChaosTrack)
  • CLIP / OWL-ViT (used in Multimodal search)
  • OpenAI API (used in ChaosTrack)
  • LLaMA 2
  • Prompt engineering (used in ChaosTrack)
  • Fine-tuning

Serving & Apps

Putting models in front of people.

  • Node.js (used in ChaosTrack)
  • Express (used in ChaosTrack)
  • GraphQL (used in ChaosTrack)
  • Hasura (used in ChaosTrack)
  • REST APIs (used in ChaosTrack)
  • JavaScript
  • Java
  • Streamlit (used in Real-time stock prediction)
  • Plotly / D3.js (used in torsha.ai)
  • TCP / UDP streaming (used in COSMOS Labs)

Two degrees, one thread

Sep 2022 – Dec 2023 · New York, NY

Columbia University (opens in new tab)

M.S. in Electrical Engineering · Machine Learning & Data Science track

  • Graduate Teaching Assistant for E4040 Neural Networks & Deep Learning.
  • Research with Prof. Zoran Kostic on the Smart City Intersections project (COSMOS Labs).
  • Columbia representative in the NSF Center for Smart Streetscapes.
  • Coursework: Statistical Learning, Natural Language Processing, Sparse Models for High-Dimensional Data, Algorithms for Data Science, Big Data Analytics.

Aug 2017 – May 2021 · Mumbai, India

University of Mumbai (opens in new tab)

B.E. in Electronics & Telecommunication

  • Ranked in the top 10% of the class.
  • Built Blind Person’s Assistant, a wearable that uses face detection and recognition to help visually impaired users.
  • Coursework: Big Data Analytics, Operations Research, Image Processing & Machine Vision, Data Compression & Encryption.

What I’m up to lately

Building
An agent that documents my lifePhone, laptop, and speech capture stitched into a searchable diary. Retrieval again, on far messier data than work.
Reading
HyperionDan Simmons. Six pilgrims, one Shrike, and a lot of pages left.
Listening
The Strokes, on repeatWith a steady diet of Desi hip hop when the volume needs to go up.
Watching
Whatever is playingBig movie buff. Strong opinions, held loosely, offered freely.
Following
Manchester City & the KnicksOne of these teams causes more stress than the other.
Playing
Chess, and guitarOpenings I know, endgames I am learning. Riffs over scales.

Updated November 2026

Let’s build somethingthat ships

Open to conversations about data science and ML engineering roles, collaborations, or a good chess game. My inbox is open.